ML pipeline and web app / in production
Dupe Engine
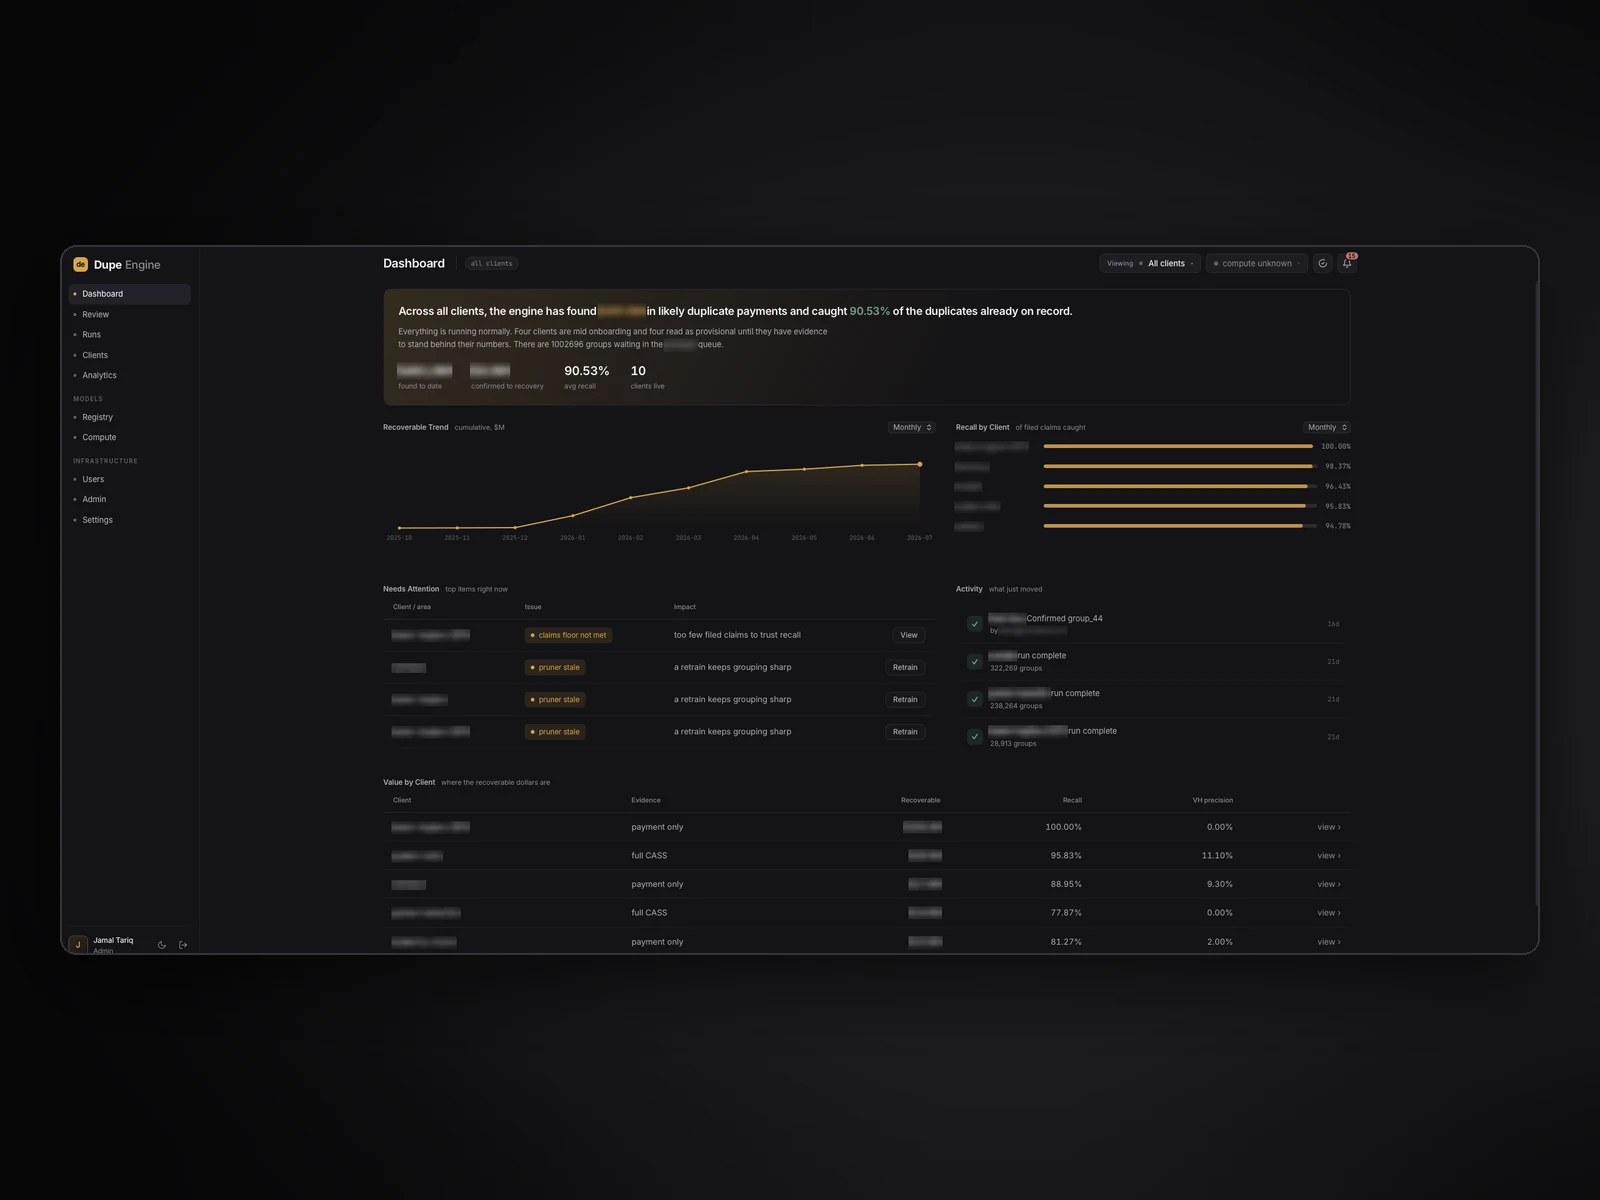
A machine learning pipeline and web app that finds freight bills a company paid twice, ranks them so the real duplicates come first and hands them off so the money can be recovered.
the problem.
Shippers sometimes pay a carrier twice for the same shipment: the invoice gets rekeyed, rebilled, split or settled twice. Across months of payment history that's a needle in a haystack and a list full of false matches wastes the verifier team's time.
how it finds them.
The pipeline reads a client's payment history and builds candidate groups month by month, with a LightGBM pruner per client and a learning to rank model on top. An ensemble then scores each group with whatever evidence the client has (EDI receipts, rate rows, charges) and sorts it into tiers.
A guard throws out groups held together by junk bill of lading numbers and fixed rules catch shapes the verifiers kept rejecting, like one payment counted twice or an invoice paid in instalments.
pair typing.
The change that lifted precision the most. Every group is split into payment pairs and each pair gets one of about 19 named shapes: exact duplicate, rekey, rebill, partial, accessorial split and so on. A LightGBM pair model, trained only on other clients so it can't cheat, orders everything in between.
Before a file ships, three orderings are compared against the client's own filed claims at six depths and the one that finds the most real duplicates goes out. On one client the top bucket went from 3,163 groups holding 32% of claims to 547 groups holding 72%.
the app.
A FastAPI and React app runs the same code as the original notebook on Azure ML. Reviewers get a keyboard driven queue, a side by side group comparison and a one click handoff to the verifier team. There's also a model registry, compute and budget tracking, Microsoft sign in and role based access for 22 features.
Verifier feedback closes the loop: wrong groupings become training negatives, wrong verdicts become rules and already recovered payments are suppressed.
how it works.
- pull months of payments and filed claims
- group payments that look like the same shipment
- score each group with the evidence on hand
- split into pairs and type each pair
- ship the order that finds the most real duplicates
- reviewers confirm, verifiers recover